Selected work
Manual processes, turned into systems.
A selection of projects from 20 years of production work at XBOX and Microsoft, a TPM role at an early-stage AI startup, and what I'm building for myself. Focused on approach and outcomes.
Ten transformations
Localization Pipeline Enhancements
XBOX localization was fragmented across surfaces, each with its own CMS and its own rules. My tooling generated localized content per surface from its own source and cut production turnaround from 30 minutes to 3.

Problem, approach, result
The problem
XBOX localization was fragmented across surfaces and systems. One surface in the XBOX app covered just 3 languages with no fallback; another already ran 30 with fallbacks, but on a different CMS. On the console there were fewer languages and variants, but strict character-width limits. Every surface had its own rules and leaned on manual copy-and-paste, and complex multi-market sales (different messaging per market) made all of it harder.
The approach
Pulling it together took several tools, refined over time. They generated localized content for each surface from its own source, added worldwide templates and fallbacks where a surface lacked them, and respected each surface's limits, whether that was language coverage or character width. Rather than start from scratch, I wrapped existing but unadopted tools in a UI and kept iterating until the whole process took minutes.
The result
The tools turned a fragmented, multi-CMS process into a consistent, largely automated one and cut manual effort on every surface. The most limited surface jumped from 3 languages to 30 and gained fallbacks it never had; the hardest multi-market sale updates dropped from 30 minutes to 3. And because content was generated from each surface's source of truth, an AI review step could verify the output against the origin (not a downstream copy) before it published.
Copilot Localization Review Agent
Localization errors were surfacing after publish. A custom M365 Copilot agent moved that review upstream, checking localized content against the source at import, before anything went live.
Problem, approach, result
The problem
Localization errors (incorrect context, the wrong language shipped to a market, off-brand terminology) were being caught late in the production cycle, sometimes after content had already published to multiple surfaces. Each catch meant updates across several markets and a manual review sweep.
The approach
The agent I set up in M365 Copilot reviewed localized content against the source at the point of import, before it entered production. It applied rules for grammar, style, sales terms, and brand terminology, then flagged issues with enough context for the producer to fix them on the spot or route them to the localization team. For the first time, producers could catch errors in languages they couldn't read, and the loc team got feedback it had never had.
The result
Manual spot-checking gave way to an automated review step. Errors that used to spread across several markets got fixed before they left the producer's hands.
AI Explorers: A Cross-Team Community of Practice
AI experiments were happening in isolation across teams. I designed and ran a weekly cross-team session where practitioners taught each other and shared best practices.
Problem, approach, result
The problem
AI tools were being adopted unevenly across the team. Enthusiasts had built sophisticated workflows while others weren't sure where to start, and there was no shared vocabulary or place to write down what worked. The gap between the people using AI well and everyone else kept growing.
The approach
I started small with a few people already experimenting with AI and grew it into a weekly cross-team session where anyone could bring a question. It wasn't top-down training. The people doing the work taught each other, while I set the agenda, picked topics (Copilot agents, Power Automate, Copilot Studio, homegrown tooling), and facilitated.
The result
It became the place our AI practice spread, person to person. A few people reached out afterward to thank me for setting it up and accelerating their learning. One of the best learnings for me personally was personal knowledge management: I'd just set up my own second brain at home, and hearing how others implemented theirs into their Microsoft work changed how I work.
Real-Time Microsoft Teams Alerts from ADO Changes
Time-sensitive campaign changes landed as a tag on a work item requiring an impossible level of attention to queries and email. I moved the alerts into Teams, sent only when action was still needed.
Problem, approach, result
The problem
A time-sensitive campaign change would land as a tag on an Azure DevOps work item and be dropped into email. As ADO notifications were easy to miss, and changes accumulated quickly in email, producers and PMs frequently checked both their inbox and a saved ADO query several times a day. Some changes needed action within the hour, which made a missed check on a busy day a real risk.
The approach
In Power Automate, I set up a flow from ADO tag to Teams message, with M365 Copilot helping me troubleshoot and refine it. When the target tag appeared on a work item, the flow checked an Excel tracker to confirm the work wasn't already handled, then sent a direct Teams alert to the responsible producers and PMs, but only when action was still needed. That meant fewer misses and less stress for everyone.
The result
The team stopped relying on memory, repeated query checks, and a cluttered inbox to catch time-sensitive work. Alerts showed up where people were already working, and only when something needed doing.
A Self-Updating Project Plan in Copilot Cowork
My editorial calendar was a color-coded Excel sheet: nice-looking, but hard to use as a plan. A Copilot Cowork agent turned it into a real project plan and kept it current on its own.
Problem, approach, result
The problem
My editorial calendar lived in Excel: color-coded and formatted as a calendar for people to read at a glance. Useful for sharing, but difficult for production planning. Turning it into an actual project plan meant reading it by hand, and it kept changing, so the plan was always in flux. I also wanted something a non-developer could run to create a plan: an alternative to VS Code and Copilot for teammates who don't live in a code editor.
The approach
When Copilot Cowork came out, I went straight to it for non-dev work. The agent connected to SharePoint, ran on a schedule, and transformed the colorful editorial calendar into a structured Excel project plan, then watched for changes and folded them back in on its own. Each morning it sent me a Teams ping listing what the day needed. It required no code editor, so I shared it with the AI Explorers team as something any PM could pick up.
The result
An ongoing manual chore became something that ran on a schedule, though, like a lot of AI tools, not perfectly. It became one of my favorite uses of agentic AI outside of coding, practical and easy to set up, even as I kept refining the prompts and waiting for the product to catch up.
XBOX Ad Preview Tool
Seeing a localized console ad meant changing the console's language and rebooting, one language at a time. Starting from nothing but an idea, I made a custom HTML tool that showed every language on one page and highlighted any copy over its character limit.
Problem, approach, result
The problem
The only way to see how localized ad copy would actually render on the XBOX console was to go into console settings, change the language, and reboot, then do it all again for the next one. Spot-checking one or two languages that way was fine, but covering 20 or so took far too long. So copy that looked fine in English could run past its character limit in German or Greek, and those catches often came too late.
The approach
The tool started with a question I asked myself. How could I preview all of our localized content, know exactly how it would render, and see it on one page I could save if needed? There was no complete spec, so working with Copilot, I created a custom HTML page from real ad placements, comparing it against the console and refining the layout until it matched almost pixel for pixel. The page rendered every supported language side by side at real display dimensions and highlighted anything that exceeded its character count.
The result
A settings change and a reboot per language became one page with every language on it and the overruns already highlighted. Reviewing 20 or so languages took a single scroll, the page could be saved whenever a record was useful, and what we approved on screen was what every market got.
A Command-Line Toolkit for a CMS with Limited Search
The XBOX Support CMS couldn't scrub its own content well. Roughly twenty command-line tools later, anyone on the team could audit content without Visual Studio.
Problem, approach, result
The problem
The XBOX Support CMS couldn't search across the full, global content areas. You could export XML, but answering a broad question (where does something appear, what's broken, what changed) meant manual investigation or one-off work in Visual Studio. Visibility across multiple content areas was poor, making routine audits surprisingly difficult.
The approach
With AI's help, I started with PowerShell scripts that parsed the CMS XML exports and grew them into roughly twenty C# command-line apps covering automated exports, regex and flexible search, and CSV and Excel reporting. Packaged as simple .exe files, they needed no Visual Studio or scripting knowledge, so teammates could run global content dashboards, broken-link audits, and configuration reports on their own.
The result
Work that had needed an expert and a lot of manual digging became something anyone on the team could run from the command line. The team could finally see across its content, and recurring audits became standard reports people ran themselves.
Meeting Recap Pipeline for Microsoft Teams
At an early-stage AI startup, only some of the team had access to Copilot meeting summaries in Microsoft Teams, and the default summary rarely said what was decided or who owned the next step. A custom recap format and a Power Automate flow gave everyone the same actionable record, and cut several minutes of manual recap work to about one.
Problem, approach, result
The problem
As a TPM at an early-stage AI startup, I was in meetings several times a week with a team that relied on the meeting summary Copilot generates in Microsoft Teams. Its default format read as a general narrative that didn't separate decisions from discussion or say who owned what next. And not everyone on the team had access to those Copilot summaries, so for some people a shared recap was the only record they got. I'd been writing, naming, filing, and announcing those recaps by hand, and with no set place or naming for them, a decision made on Monday was hard to find by Thursday.
The approach
I started with the format, a custom Markdown layout for the Teams Copilot summary that organized each recap around decisions, priorities, and tasks. Tasks came out as a table with a title, description, assignee, priority, and due date for each one. Then I set up a manually triggered Power Automate flow. After a meeting I ran it, typed a title, and pasted in the notes, and the flow created a predictably named .md file in the right SharePoint library and posted a link in the team's Teams chat.
The result
What had taken several minutes of manual work after each meeting took about a minute. Every meeting ended with the same kind of recap, in the same place, under a name you could guess, and the whole team heard about it right away, including the people without Copilot in Teams. Because the recaps were consistent, decisions and action items were easy to follow from one meeting to the next, and when a task belonged in Microsoft Planner, I copied it over straight from the table. Markdown also meant a recap could go straight into a notes system or an AI tool without conversion.
Personal Job Board
Personal build · Python · local LLM · 2026
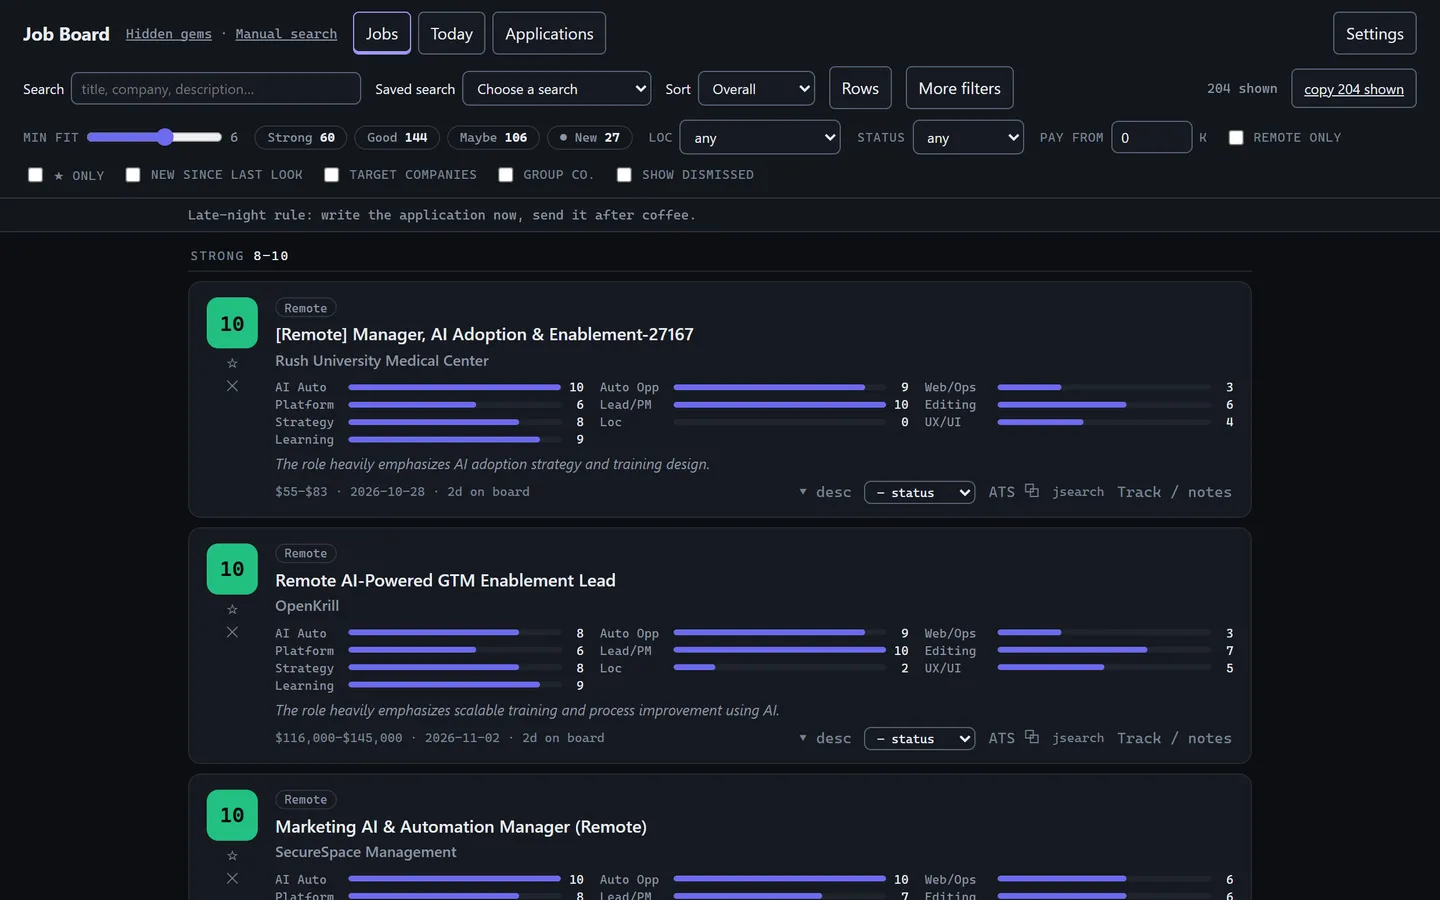
A serious job search means watching a dozen-plus sources daily and reading fifty postings to find three that match my interests. Now a pipeline collects, dedupes, and scores every posting with a local LLM against nine weighted axes, then sends the best few to my phone.
Problem, approach, result
The problem
I'm trying to simplify how I look for jobs by creating a tool just for myself. I want to watch a dozen-plus sources (government job feeds, company boards on Greenhouse and Workday, USAJobs, aggregators) every day. The same posting appears on three of them under slightly different titles. And "is this worth applying to?" is a judgment call across many dimensions at once: how central each of my skills is to the role, where it sits, whether it quietly wants a hands-on engineer instead of an orchestrator. Reading fifty postings to find three good ones is exactly the kind of manual process suited to an LLM, and exactly what I need it for.
The approach
So I built the tool I wanted: a Python pipeline that collects from eight kinds of source, dedupes across them (same company + title + city, keeping the richest record), then scores every posting with a local LLM against nine weighted "centrality" axes. Two adjustments follow. One asks where the job is and how often it wants me onsite. The other encodes what I'm not (hands-on IC engineering ×0.35, visual design ×0.5). The two heaviest axes are AI Automation and Automation Opportunity, so a role drowning in manual process scores high, because that's a primary interest of mine. Scores are cached, so a run only evaluates what's new. I designed the pipeline and the scoring model; AI wrote most of the implementation under my direction, which is rather the point. Probably obvious, but this is one of my favorite uses of AI: make your own tools! Companion tools compare any posting against my résumé, report the gaps, and build a tailored copy that stops if it meets a number my real résumé can't back up.
The result
One command produces a ranked, self-contained dashboard. A Telegram bot sends the top matches to my phone in the voice of Red Dwarf's Queeg, and tells me if a run hangs. A second page covers the places with no sanctioned feed, like LinkedIn and Indeed: links I click myself, each with a note on why it isn't automated. A daily hidden-gems pass picks out strong roles the adjustments may have buried and files them in a log, which opens with a few lines from the local model in the manner of Douglas Adams. When I pick a role, the board tracks it from interested to offer, with follow-up dates and notes. My fit judgment lives in a config file instead of my head, so tuning it is an edit, not a habit. And because the scoring runs on a local LLM, ranking costs nothing and the scoring never leaves my machine.
How I check it
A tool that ranks my job search needs checking, so I measure it against things it can't see. In September I compared it with a one-off manual look at LinkedIn's "top applicant" list. The board had seen only 19 of those 113 roles, which told me which employer boards to add. The ones it had scored averaged 6.9 out of 10, against 3.1 for the board as a whole, so two independent judges mostly agreed on fit. A state web-content role had the highest base score on the board and showed up as a 1, because the model was answering "where is it?" and "how often onsite?" with one field. I split them. And when listings seemed to be drying up, counting the same employer boards day over day showed the drop came from my own title filter. The market was flat.

Meeting Transcriber
Personal build · Python · local models · 2026
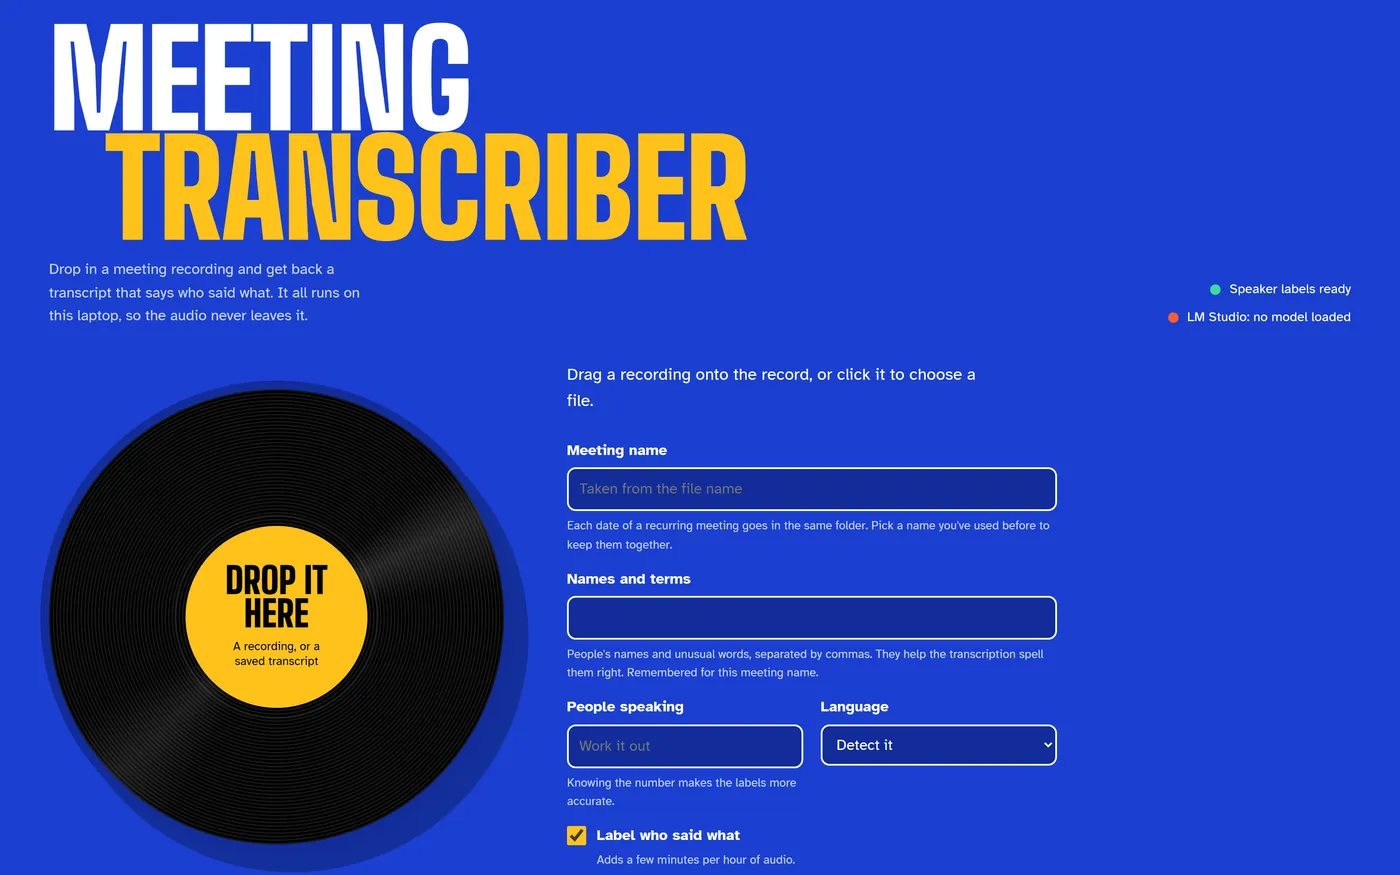
An hour-long meeting deserves a better record than my memory of it. Now I drop the recording on a page and get back a Markdown transcript with every speaker labelled, plus meeting minutes from a local model if I want them. It all runs on my laptop, so the audio never leaves it.
Problem, approach, result
The problem
I needed a transcript of an hour-long meeting, and I wanted who said what, not one long wall of words. Cloud services will do it, but that means uploading other people's conversation to someone else's servers. The usual open-source route, WhisperX, pins its own versions of the libraries underneath it and fights Windows and newer GPUs. And the transcript is the easy half. People rarely say "action item," so the minutes have to work out what was decided, who volunteered, and what was only floated.
The approach
The pipeline pairs faster-whisper for the words with pyannote for who spoke when, then merges the two itself. Where people talk over each other, the speaker model sometimes hands a few words of one person's sentence to someone else, so those fragments get folded back into the sentence they interrupted. A drag-and-drop page, designed like a jazz record sleeve, does the rest: drop a recording on the vinyl, name each speaker from their longest lines (with a play button for each), and save to Markdown, Word, an HTML page, plain text, or OneNote. Each meeting gets its own folder by name and date, and a list of past meetings reopens any of them without transcribing again. A names-and-terms box gives Whisper hints, which is how "John" finally became Jon. Minutes come from whichever model is already loaded in LM Studio, in four formats: action minutes, highlights, a decision log, and a follow-up email draft. It runs on the CPU by default, because my laptop has a history with heavy GPU loads.
The result
An hour of meeting takes about 15 to 20 minutes on the laptop's CPU, plus the speaker step, and comes back as a Markdown file with real names that drops straight into my notes or any AI tool. Nothing is uploaded: the page works on a copy of the recording and deletes it when it's done. Every next step in the minutes says how firm it is (Committed, Offered, or Suggested), because the gap between "I'll do it" and "we should" is most of what a recap is for.
How I check it
The first real test was a 64-minute meeting, and the minutes said there were no actions and no decisions, and listed nothing between minute 24 and minute 54. The model hadn't summarized too much; it had lost the middle. So now it reads the meeting in ten-minute parts, takes notes on each, and merges the notes by reference, and any commitment the merge drops is added back. Every item cites where it was said, and a cited time has to land within two seconds of a real transcript line or it's flagged before I share anything. "Committed" has to trace back to the owner actually speaking at that moment, or it's downgraded to Offered. I ran that same meeting through three local models: the slowest took 25 minutes and was the most faithful, the fastest took 95 seconds and was the most cautious, and the one in between wrote the most detail but made people sound more in agreement than they were.